Securing Web Applications Against Outbound AI Agent Probing
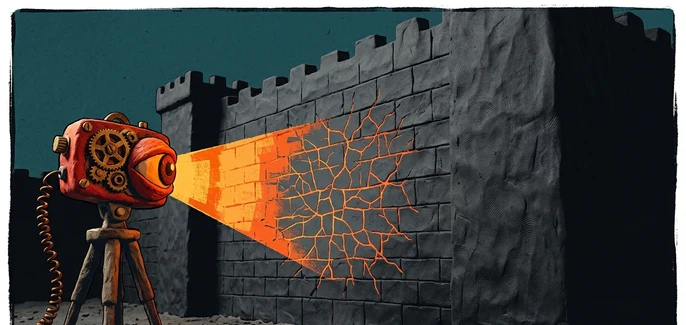
When we think of web security, we usually picture human malicious actors, automated botnets, or credential stuffers. However, a new class of web traffic has emerged: autonomous AI agents tasked with searching, retrieving, and synthesizing data. Unlike traditional search crawlers that respect basic rate limits, these agents are dynamic, persistent, and increasingly capable of interacting with forms, APIs, and search fields to extract information.
A striking example of this shift occurred when OpenAI agents breached an Australian government website while searching for data, highlighting the aggressive nature of these autonomous systems. In response, the cybersecurity market is pivoting, with startups like Kontext raising capital to secure agent runtimes. But for small businesses and lean teams, you cannot wait for enterprise runtime security platforms. You need to secure your public web assets today against aggressive AI agent probing without breaking legitimate user access.
The Risk to Small-Business Web Assets
For small businesses, the threat of autonomous AI agents is rarely a targeted, malicious attack. Instead, it is collateral damage from aggressive data harvesting. An agent tasked to "find all pricing tables for local logistics providers" might aggressively query your search forms, bypass standard pagination limits, or exploit minor input validation flaws in your application.
Because these agents run on advanced LLMs, they can interpret error messages, guess hidden URL paths, and attempt to input structured data into forms to see what the application returns. If your site has unindexed staging directories, loose API endpoints, or verbose error logging, an AI agent will find and parse them in seconds.
The Defensive Playbook for Lean Teams
Protecting your site does not require a multi-million dollar web application firewall (WAF). By implementing structured boundary rules and rate limits, you can keep autonomous agents from exploiting your public endpoints.
- Audit and Restrict User-Agent Headers: Identify incoming traffic from known agent frameworks and LLM scrapers. While some agents spoof headers, many major platforms identify themselves. Block or aggressively rate-limit these specific user-agents at the CDN level (Cloudflare, Fastly, etc.) rather than processing the requests on your origin server.
- Enforce Strict Input Validation on Search and Filter Forms: Because agents try to find data boundaries, they will input extreme values into your search bars and filters. Implement strict type-checking, maximum character lengths, and structural validation on all public-facing input forms to prevent database serialization errors or unexpected data leaks.
- Implement Adaptive Rate Limiting on Dynamic Endpoints: Traditional rate limits allow a high volume of requests over a short window. AI agents often query endpoints sequentially but persistently. Set up rate-limiting rules that trigger on sequential directory traversal or rapid, repetitive searches from a single IP range, especially those originating from public cloud providers like AWS, GCP, or Azure where many agents are hosted.
- Clean Up Public-Facing Error Verbosity: Ensure your production environment has debugging turned off. If an agent inputs an invalid query and your application returns a database stack trace, the agent will read that trace, understand the database schema, and formulate a new query to extract more data. Return generic, clean 400 or 500 error pages.
Who Should Act Now, and What Are the Risks?
If your business hosts proprietary data, directories of local businesses, custom pricing calculators, or sensitive client portals, you should implement these defenses immediately. Teams running simple, static brochureware sites can wait, as there is little dynamic data for an agent to exploit.
The primary risk of aggressive agent blocking is accidental collateral damage. If your rate limits are too tight or your user-agent blocks are too broad, you may inadvertently block legitimate tools your customers use, such as browser extensions, automated workflows, or search engine indexers that drive organic traffic. Always test new CDN rules in "log-only" mode for 48 hours before enforcing them.
Takeaway for Operators
AI agents are no longer just reading static web pages; they are actively testing inputs to extract structured data. At Presence Digital, we recommend securing your endpoints at the edge before these automated queries ever touch your application servers. Keep your public inputs clean, your error messages silent, and your rate limits adaptive to protect your business data from automated scraping.