How to Build a RAG Software Factory for Reliable AI Products
A RAG prototype can look convincing in a meeting and still be difficult to trust, update or operate a month later. The difference between a promising demo and a dependable AI feature is rarely just a better model. It is a repeatable way to turn approved information into a tested, monitored service.
That is what a software factory for generative AI means: a standard set of steps, controls and reusable components for building and shipping AI features, rather than a fresh collection of scripts for every experiment. For a small or mid-sized company, the goal is not an elaborate platform. It is a reliable path from business need to a feature that can be changed safely.
What the factory standardises—and what RAG does
A software factory standardises the work around an application: how data is prepared, how changes are tested, how releases are approved and how problems are observed. It does not mean every use case must use the same model, prompt or retrieval strategy. Standardise the process and safeguards; leave room for the right design at each stage.
Retrieval-augmented generation, or RAG, is one pattern within that process. When someone asks a question, the system searches a collection of relevant material, then gives selected passages to a language model as context for its answer. The model can produce a useful response grounded in that material instead of relying only on what it learnt during training.
For example, an internal policy assistant might retrieve approved procedures and answer a staff member’s question with references to the relevant sections. RAG does not make the answer automatically correct: the source may be incomplete, retrieval may miss the right passage, or the model may misinterpret it. A factory makes those failure points visible and testable.
The decision for leaders is whether a recurring information task merits an operational AI feature—and, if so, whether the organisation can maintain its data, controls and evaluation over time. If the task is a one-off experiment with no owner or reliable source material, a production pipeline is premature.
Build a dependable path from data to answers
A useful RAG factory has distinct components, even when a managed service combines several of them. Keeping the responsibilities clear makes it easier to replace a component or investigate a bad answer without rebuilding everything.
- Ingestion and connectors: Collect material from approved sources such as document stores or internal knowledge systems. Record where each item came from, when it changed and who may access it.
- Chunking and embeddings: Split documents into passages that preserve enough context to be useful, then represent those passages as numerical embeddings for similarity search. Chunking choices affect both what retrieval finds and how much context reaches the model.
- Vector store and retrieval: Store and search the embeddings, usually alongside the original text and its metadata. Apply filters for permissions, dates or other relevant attributes before returning passages.
- Re-ranking: When the initial search returns several plausible passages, a re-ranking step can sort them by likely relevance. It may help when search results are noisy, but it adds operational complexity and can increase latency.
- Prompt templates and LLM orchestration: Assemble the question, retrieved material and instructions into a controlled request. Orchestration manages the flow between retrieval, model calls, validation and any fallback behaviour.
- Guardrails, evaluation and observability: Guardrails set boundaries on inputs and outputs. Evaluation checks retrieval and answer quality against known examples. Observability records operational signals—such as failures, response times and token use—without exposing sensitive content unnecessarily.
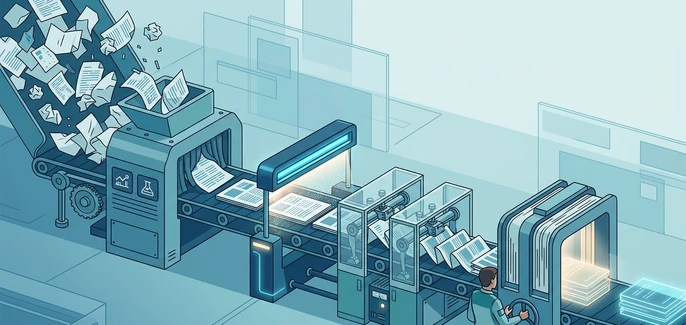
The end-to-end workflow is straightforward to describe: ingest source material, index it, retrieve relevant passages, generate an answer, evaluate the result, deploy the feature, monitor its behaviour and iterate. In practice, each hand-off needs a clear owner and a way to detect failure. A successful index build, for instance, does not prove that the system retrieved the right policy for a particular person.
Put the work into a practical delivery sequence
Start with one bounded use case, such as finding approved guidance for a defined group of employees. Avoid beginning with a company-wide assistant that must answer every question from every source. A narrow scope makes it possible to test value, access rules and failure cases before multiplying them.
- Choose the task and its owner. Write down who will use the feature, what decision or task it supports, and what a useful answer looks like. Name a business owner responsible for the source material and a technical owner responsible for the service. Define what the system must do when it cannot find adequate evidence.
- Prepare and govern the data. Identify the authoritative sources, remove or exclude obsolete material, and agree how updates and deletions reach the index. Preserve source identifiers and access metadata. Confirm that the intended use is permitted and that sensitive information is handled under the company’s existing policies.
- Build a thin, testable RAG path. Connect one or two sources, establish a simple chunking and retrieval approach, and use a prompt that requires answers to stay within the supplied evidence. Return source references where practical. Add access checks before retrieved content is passed to the model, not only after an answer is generated.
- Evaluate before widening access. Create a small set of realistic questions, including ambiguous, unanswerable and access-restricted cases. Review whether the right passages were retrieved separately from whether the final answer was accurate and appropriately cautious. Have knowledgeable people judge the outputs; automate repeatable checks where the expected result is clear.
- Release gradually and learn. Deploy to a limited group, monitor errors, latency, cost and feedback, then review failures with the owners. Fix weak sources or retrieval before reaching for a more complex model. Expand only when the feature meets agreed quality and operational expectations.
This sequence is deliberately modest. It creates reusable steps without requiring a large internal platform team. A factory can begin as a documented checklist, shared code and a repeatable deployment process; automate the parts that are repeated often enough to justify it.
Design for change, safety and sustainable ownership
Data quality and governance: RAG can surface outdated, contradictory or poorly structured material very efficiently. Set an authoritative source for each content type, define how changes flow into the index, and decide how quickly removed content must stop appearing. If nobody owns the source, do not treat an index refresh as a substitute for governance.
Security and access control: Retrieval must respect the permissions of the person asking the question. Filtering results after retrieval can be too late if restricted passages have already reached a model. Test access boundaries with realistic user roles, and consider how indexing, logs and model providers handle sensitive content. Retrieved documents can also contain misleading instructions; treat their contents as data, not as authority to override system controls.
Cost and latency: Each step can add work: connector calls, embedding generation, search, re-ranking and model generation. Measure the full request path on representative questions. Cache only where the content, permissions and freshness requirements make it safe. Do not add a re-ranker or longer context by default; first check whether it improves answers enough to justify the extra time and expense.
Evaluation and human review: A few impressive demonstrations are not an evaluation plan. Keep a versioned set of representative and difficult questions, with expected source material and review criteria. Measure retrieval quality and answer behaviour separately. Human review remains important for consequential outputs, changing source material and cases where a wrong answer could cause harm. Make it easy to report an unhelpful or unsafe response.
Versioning and observability: Record which source snapshot or index version, prompt version, retrieval settings and model configuration produced an answer. That makes regressions easier to trace and roll back. Monitor operational health as well as quality signals, while limiting logged content to what is necessary and permitted. Treat prompts and indexes as release artefacts, not invisible configuration.
Build versus buy: Buy or use managed components when they meet your security, access, integration and operating requirements; building every layer is rarely the maintainable choice for a small team. Build custom components when a specific requirement cannot be met safely or reliably with available tools, and keep the custom surface narrow. In either case, retain ownership of the data flow, evaluation, access policy and release process.
Act now if you have a well-defined task, an accountable owner and trustworthy source material, and can test who should see what. Wait if the data is uncontrolled, the desired outcome is vague, or there is no capacity to review failures and maintain the feature. The main limitation to remember is that a RAG pipeline can improve grounding, but cannot guarantee that retrieved information is complete or that generated answers are correct.
For operators and builders, the takeaway is simple: make the path repeatable before making it bigger. Pick one useful task, name its owners, and test the data-to-answer journey end to end.
Newsletter
New articles, in your inbox
One email when we publish. No digests and no product pitches. Unsubscribe any time. Privacy policy